INTRODUCING PREAMP
Fewer Tokens.
Better Margins.
AI applications often send more context to foundational models than their tasks require. PreAmp identifies the evidence needed for each question before it reaches the model.
Less context means lower inference cost.
Designed to work with existing retrieval and RAG workflows.
WHERE IT FITS
Built for context-heavy AI.
PreAmp is built for AI applications that work with large amounts of text.
- Large proprietary document collections
- Frequent questions against the same corpus
- Long retrieved contexts
- High inference volume
- Costs that rise with model usage
- Answers that must remain accurate and well-supported
Potential applications include legal and professional services, intelligence and defense, scientific and technical research, enterprise knowledge systems, and other document-intensive AI products.
PREAMP
How PreAmp works.
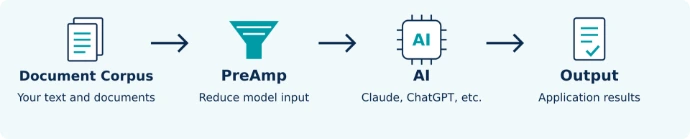
PreAmp prepares document collections ahead of time, then identifies the source evidence needed for each question before sending context to the model.
CORPUS
Prepared document corpus
Processed ahead of time for fast evidence selection
PREAMP
Relevant source evidence
Selected for each question
MODEL
Foundational model
Receives only the context needed for the question
Prepare once
Document collections are processed ahead of time.
Question-specific
PreAmp selects source evidence for each question.
Fits existing RAG
PreAmp works after retrieval rather than replacing it.
Model-agnostic
Use the foundational model that fits the application.
VALIDATION
Up to 90% less context sent to the LLM
Internal benchmark results under tested conditions.
WHAT WE MEASURE: Cost per accurate, complete, evidence-supported answer.
Results vary by corpus, task, model, and deployment.
Built on research.
Focused on economics.
PreAmp builds on more than a decade of DARPA-funded R&D in language understanding and information processing.
Causerie.ai is bringing that work into commercial and government applications where model cost, scale, and answer quality matter.
CONTACT
Working with large amounts of text?
We’re looking for applications where PreAmp can be tested against real workloads.